Learning Multiple Initial SOlutions to Optimization Problems
1Technion2NVIDIA Research3Harvard University4Stanford University
ICRA 2026
Overview
Many real-world applications—from autonomous driving to robotic manipulation—require solving similar optimization problems sequentially under strict runtime constraints. The performance of local optimizers is highly sensitive to the initial solution: poor initialization can lead to slow convergence or convergence to suboptimal local minima.
We propose MISO (Learning Multiple Initial SOlutions), a framework that trains a single neural network to predict multiple diverse initial solutions for optimization problems. Unlike ensemble methods that require training and running multiple models, MISO uses a single efficient network with diversity-promoting training objectives.
- Single-optimizer setting: Select the most promising initial solution using a selection function, then run a single optimizer.
- Multiple-optimizers setting: Initialize multiple parallel optimizers, each with a different predicted solution, and select the best final output.
- Guaranteed improvement: By including the default initialization among predictions, MISO is guaranteed to perform equal or better than baseline.
- Efficient inference: Unlike ensembles, MISO's inference time remains nearly constant as $K$ increases.
1 Motivation
Consider an autonomous vehicle following a planned trajectory. Suddenly, a pedestrian steps onto the road, causing the high-level planner to abruptly change the reference path. The previous trajectory (warm-start) is now far from optimal—the optimizer must find a completely different solution within milliseconds. Similar abrupt changes occur with traffic light switches, sudden lane closures, or newly detected obstacles.
Traditional initialization approaches fail in these scenarios:
- Warm-start: Reuses the previous solution, which becomes invalid after abrupt changes.
- Single-output regression: Learns to predict the mean of multiple modes, often corresponding to a local minimum.
- Ensemble of regressors: Each model is biased toward the same mean, failing to cover multiple modes.
By explicitly training for diversity using winner-takes-all or mixture losses, MISO learns to cover multiple modes of the solution distribution, enabling the optimizer to reach global optima regardless of which mode is active.
2 Method
Given a parameter vector $\boldsymbol{\psi}$ that defines a problem instance (e.g., current state, goal, obstacles), our multi-output predictor outputs $K$ candidate initial solutions:
Training strategies
To ensure diverse outputs that cover multiple modes, we introduce three training strategies:
Winner-takes-all (WTA) loss
Only penalize the best-predicted output, allowing other outputs to specialize on different modes:
Pairwise distance (PD) loss
Add a term to encourage dispersion among outputs:
Mixture loss
Combine WTA with pairwise distance for enhanced diversity control:
Selection function
In the single-optimizer setting, a selection function $\Lambda$ chooses the most promising initial solution. A natural choice is selecting the candidate that minimizes the objective: $\Lambda := \arg\min_{k} J(\hat{\boldsymbol{x}}_{k}^{\mathrm{init}}; \boldsymbol{\psi})$. Alternative criteria include constraint satisfaction, robustness measures, or domain-specific requirements.
3 Experiments
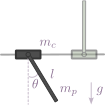
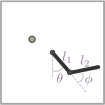
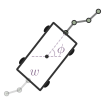
We evaluate MISO across three optimal control benchmark tasks, each using a different local optimization algorithm:
Main results
Single optimizer setting
| Method | K | One-Off Optimization | Sequential Optimization | ||||
|---|---|---|---|---|---|---|---|
| Reacher | Cart-pole | Driving | Reacher | Cart-pole | Driving | ||
| Warm-start | 1 | 13.48 | 11.69 | 283.86 | 13.48 | 11.69 | 283.86 |
| Regression | 1 | 13.40 | 11.19 | 74.23 | 19.56 | 6.18 | 70.62 |
| Ensemble | 32 | 13.39 | 10.94 | 47.22 | 8.40 | 3.55 | 52.59 |
| MISO WTA | 32 | 13.36 | 10.48 | 30.17 | 2.72 | 0.83 | 30.75 |
| MISO mix | 32 | 12.74 | 10.48 | 33.95 | 2.44 | 0.79 | 33.38 |
MISO WTA and MISO mix consistently outperform all baselines. On the challenging driving task, MISO reduces mean cost by 89% compared to warm-start and 42% compared to ensemble methods in sequential optimization.
Scaling with number of initial solutions
(a) Single optimizer
(b) Multiple optimizers
Inference time comparison
Mode frequency analysis
4 Qualitative results
(a) Driving, single optimizer
(b) Cart-pole, multiple initial solutions
5 Visualizations
Citation
@article{sharony2024learningmultipleinitialsolutions,
  title={Learning Multiple Initial Solutions to Optimization Problems},
  author={Elad Sharony and Heng Yang and Tong Che and Marco Pavone and Shie Mannor and Peter Karkus},
  journal={arXiv preprint arXiv:2411.02158},
  year={2024},
}References
- Amos, B., et al. (2018). Differentiable MPC for end-to-end planning and control. NeurIPS.
- Williams, G., et al. (2015). Model predictive path integral control using covariance variable importance sampling. arXiv:1509.01149.
- Li, W., & Todorov, E. (2004). Iterative linear quadratic regulator design for nonlinear biological movement systems. ICINCO.
- Caesar, H., et al. (2021). nuPlan: A closed-loop ML-based planning benchmark for autonomous vehicles. CVPR Workshop.
- Guzman-Rivera, A., et al. (2012). Multiple choice learning: Learning to produce multiple structured outputs. NeurIPS.