VLM-Guided Experience Replay
1Technion2ForSight Robotics3NVIDIA Research
Overview
VLM-RB uses a frozen, pre-trained Vision-Language Model (VLM) as an automated evaluator that identifies and prioritizes promising sub-trajectories in the replay buffer of an off-policy agent. Prior work has integrated LLMs and VLMs into various components of reinforcement learning, but the replay buffer, the component that stores and reuses experience, has remained unexplored. VLM-RB is a plug-and-play prioritization layer for any off-policy algorithm that uses one.
Experience replay[2] is fundamental to off-policy RL, but which experiences should be prioritized? Prioritized Experience Replay (PER)[1] favors transitions with high temporal-difference (TD) error. TD error can correct value estimates, but it lacks semantic awareness: it cannot distinguish transitions that reflect genuine progress toward task completion from those that do not.
This limitation is acute in long-horizon, sparse-reward tasks. Critical transitions, such as unlatching a door or grasping a tool, may yield low TD errors early in training, because delayed credit assignment has not yet propagated the reward to them. Conversely, visually distinct but task-irrelevant motions can yield large TD errors despite contributing little to task completion.
- 15–57% higher average success rates than uniform and prioritized experience replay, in discrete game-playing and simulated continuous-control manipulation
- 35–55% better sample efficiency: fewer steps to reach the baselines’ best performance
- Matches or exceeds every baseline in success and improves sample efficiency in 23 of 24 comparisons
- No fine-tuning required — uses frozen, off-the-shelf VLMs
- ~12% throughput overhead via asynchronous VLM scoring
1 Method
VLM-RB is a plug-and-play framework for any off-policy algorithm that leverages a replay buffer. A VLM assigns semantic scores to sub-trajectories, and sampling is biased toward higher-scoring experiences during policy optimization.
Pre-trained VLMs already encode rich semantic priors about what constitutes meaningful behavior. VLM-RB can therefore immediately identify semantically relevant data, enabling faster learning than approaches which must wait for the critic to converge.
Scoring
VLM-RB extracts semantic scores from collected experience with a frozen, pre-trained VLM. Let $\tau^O_i=(o_{i}, o_{i+1}, \ldots, o_{i+L-1})$ denote a visual clip of $L$ rendered frames. The VLM maps this clip and a text prompt $\mathsf{P}$ to a scalar score:
The prompt is goal-agnostic and domain-generic (see the environments below). Because the VLM is frozen and its evaluation depends only on static visual content, each clip is scored exactly once, whereas PER must keep updating priorities as the value function evolves.
Why clips rather than frames? A single frame is fundamentally limited by semantic ambiguity: a gripper hovering above an object looks the same at the onset of a successful grasp and in the aftermath of a failed attempt. Scoring sub-trajectories gives the VLM the temporal context to tell meaningful behavior from failure.
Value?
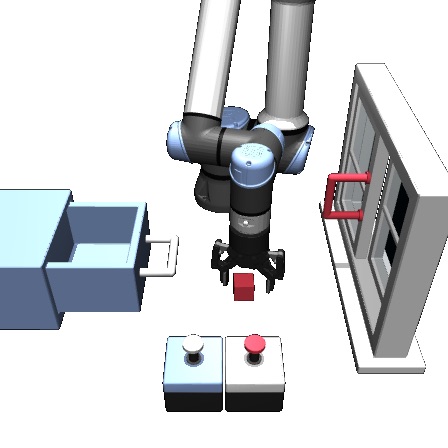
$o_i$
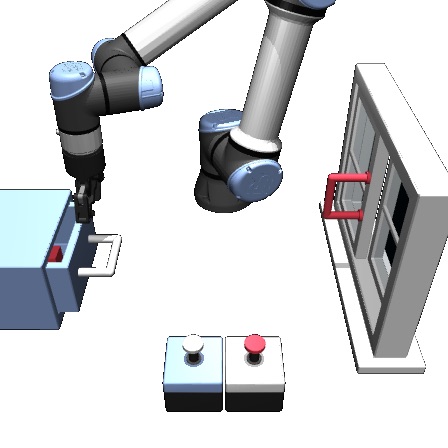
$\tau^O_{i,1}$ · successful grasp
The gripper grasps the cube and carries it into the drawer.
High VLM score
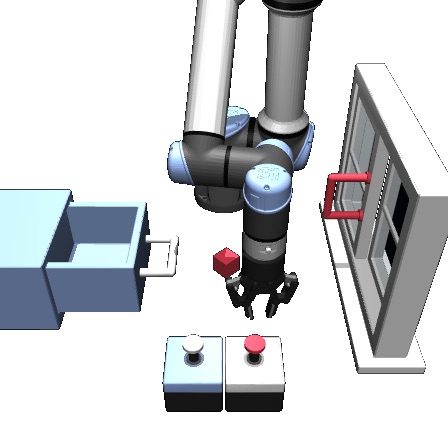
$\tau^O_{i,2}$ · stagnation
The arm moves, but the cube stays where it was.
Low VLM score
Prioritization
The VLM score of each clip is propagated to all transitions within that clip and combined multiplicatively with the latest TD error. This defines the priority signal, which is converted into a distribution:
The two factors carry complementary information: $p^{\text{VLM}}_i$ marks which experiences are semantically consistent with task success, whereas $|\delta_i|$ marks where the value function is still inaccurate.
Sampling
Because the VLM is an external prior that may score useful transitions inaccurately, VLM-RB preserves full-buffer coverage by mixing VLM-guided prioritization with uniform replay:
Each batch draws a $\lambda_t$ fraction from $q^{\mathrm{P}}_t$ and the remainder uniformly. A linear warm-up starts at $\lambda_0=0$ (pure uniform sampling) and anneals to $\lambda_{\max}=0.5$ over the first half of training: the warm-up favors broad coverage early on, and the uniform component limits the influence of inaccurate VLM scores throughout.
Efficient implementation
The VLM scores clips asynchronously, in the background, so policy optimization is never blocked by inference latency. A transition enters the buffer with a provisional score $\bar{p}$, the running mean of the VLM scores returned so far, and the clip’s own score overwrites it once the worker returns. The scorer is a lightweight 1B-parameter Perception-LM[4].
2 Experiments
We compare VLM-RB with uniform (UER) and prioritized (PER) experience replay under four algorithms: DQN[7] and IQN[8] on MiniGrid, and SAC[9] and TD3[10] on OGBench. Agents receive state-based observations rather than pixels, isolating the effect of replay prioritization; only the VLM sees rendered frames. We report the average success rate (ASR) over 32 evaluation episodes per seed, averaged over 5 seeds, with the standard error of the mean.
Environments
Discrete navigation with sequential subtasks: pick up the key, unlock the door, reach the goal. Rewards are sparse: zero at every intermediate step, and positive only at the goal.
Prompt: "Does this clip contain a clear instance of goal satisfaction anywhere in it? If no visible success occurs, answer No. Do not guess. Output exactly Answer: Yes or Answer: No."
Continuous tabletop manipulation with a UR5e arm: a cube, a drawer, a window, and two buttons that lock them. Tasks 3–5 require increasingly long compositional sequences of unlocking, placing, and relocking. All methods share a warm start of 10 demonstration episodes.
Prompt: "Is there at least one clear instance of goal satisfaction in these frames? Look for contact + displacement consistent with the goal (lift off surface, place into receptacle, open/close articulation, move to target zone). Do not guess. If not visible, answer No. Output exactly Answer: Yes or Answer: No."
Frozen VLM scores qualitatively anticipate learned value
Does the VLM offer a useful signal before any learning happens? To illustrate the semantic grounding of our prioritization, we compare the frozen VLM scores with critic value differences ($\Delta Q$) as learning progresses, on a fixed reference episode and with checkpoints from a successful training run. The critic’s estimates are initially flat and uninformative; over training, it gradually learns to assign high value to the same semantic events, such as picking up the key or opening the door, that the VLM identified from the outset.
clip (32 steps) stand-in actions whole path
Semantic prior
Following the “Modified Game” paradigm[14], we modify only the rendered frames used for VLM scoring, leaving the MDP and the agent’s observations untouched. In the Misleading game, object sprites are swapped for semantically conflicting ones, such as keys rendered as lava; in the Abstract game, objects are replaced with noise patterns. Both slow learning and increase variance, and with abstract visuals performance degrades to the level of PER (Figure 5): the prioritization is only effective when the visual input aligns with natural semantic priors.
Main results
VLM-RB matches or exceeds every baseline in success and improves sample efficiency in 23 of 24 comparisons. The largest gains appear in the most challenging settings: on DoorKey-16x16, VLM-RB achieves a +283.3% improvement over UER and +91.7% over PER; on Scene-5, the improvement is +147.2% over UER and +67.9% over PER. Even where the baselines eventually solve the task, VLM-RB reduces the number of steps needed to reach their best performance by as much as 62.0%.
| Algorithm | Level | vs. UER | vs. PER | ||
|---|---|---|---|---|---|
| Performance ↑ | Sample efficiency ↓ | Performance ↑ | Sample efficiency ↓ | ||
| DQN + IQNDoorKey | 8×8 | 0%(1.00/1.00) | 22%(139K/178K) | 0%(1.00/1.00) | 26%(139K/187K) |
| 12×12 | 61%(1.00/0.62) | 57%(277K/640K) | 22%(1.00/0.82) | 37%(292K/467K) | |
| 16×16 | 283%(0.92/0.24) | 53%(420K/893K) | 92%(0.92/0.48) | 51%(305K/622K) | |
| SAC + TD3Scene | 3 | 0%(1.00/1.00) | 40%(213K/354K) | 0%(1.00/1.00) | 20%(213K/266K) |
| 4 | 22%(1.00/0.82) | 62%(295K/776K) | 2%(1.00/0.98) | 38%(394K/634K) | |
| 5 | 147%(0.89/0.36) | 55%(366K/819K) | 68%(0.89/0.53) | 37%(508K/805K) | |
Comparisons and ablations
Beyond uniform and prioritized replay, we compare VLM-RB with alternative prioritization schemes, and ask which of its design choices matter: the priority signal, the sampling mixture, and the size of the VLM.
VLM-RB is the only method to consistently solve DoorKey when compared with Attentive Experience Replay (AER)[11], Experience Replay Optimization (ERO)[12], and Reducible Loss Prioritization (ReLo)[13]. ERO and ReLo fail to prioritize task-relevant transitions because their feedback signals are either dominated by noise or remain zero throughout the long pre-success phase, while similarity-based methods like AER over-sample current states and neglect critical past dependencies such as key acquisition.
To compare the two factors of the priority, we evaluate uniform replay, TD-only priority, VLM-only priority, and their product on DoorKey-16x16 with DQN and Scene-5 with SAC. The VLM-only priority exceeds both baselines on both tasks. Multiplying it by $|\delta|$ leaves the DoorKey result unchanged and improves Scene-5 from 0.88 to 0.94 ASR, while reducing the steps to PER’s best performance from 670K to 440K. We therefore use the product in the main experiments.
| Priority | DoorKey-16x16 | Scene-5 |
|---|---|---|
| UER | 0.20(920K, never) | 0.44(900K, never) |
| PER (TD-only) | 0.76(330K, 850K) | 0.62(570K, 970K) |
| VLM-only | 1.00(310K, 410K) | 0.88(470K, 670K) |
| $p^{\text{VLM}}|\delta|$ (VLM-RB) | 1.00(310K, 410K) | 0.94(320K, 440K) |
A central component of our approach is to mix VLM-scored samples with uniformly sampled data, allowing the external semantic prior to guide replay while preserving uniform coverage. To assess its importance, we vary the maximal mixing coefficient $\lambda_{\max}$, holding all other parameters fixed. The no-mixture configuration (pure priority from the first update) fails to solve DoorKey-16x16, whereas the scheduled configurations succeed, showing the importance of mixing VLM-prioritized and uniform replay during training.
Scaling the VLM beyond 1B parameters dramatically increases computational cost without yielding consistent improvements in downstream RL performance. Relative to the 1B model, the 3B variant increases peak memory by 116% and reduces throughput by 40%; the 8B variant increases peak memory by 439% and reduces throughput by 79%.
Citation
@article{sharony2026vlm,
  title={VLM-Guided Experience Replay},
  author={Sharony, Elad and Jurgenson, Tom and Krupnik, Orr and Di Castro, Dotan and Mannor, Shie},
  journal={arXiv preprint arXiv:2602.01915},
  year={2026}
}References
- Schaul, T., et al. (2015). Prioritized Experience Replay. arXiv:1511.05952.
- Lin, L.-J. (1992). Self-improving reactive agents based on reinforcement learning, planning and teaching. Machine Learning.
- Radford, A., et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. ICML.
- Cho, J.H., et al. (2025). PerceptionLM: Open-Access Data and Models for Detailed Visual Understanding. arXiv.
- Chevalier-Boisvert, M., et al. (2023). Minigrid & Miniworld: Modular & Customizable RL Environments. NeurIPS.
- Park, S., et al. (2024). OGBench: Benchmarking Offline Goal-Conditioned RL. arXiv.
- Van Hasselt, H., Guez, A., and Silver, D. (2016). Deep Reinforcement Learning with Double Q-Learning. AAAI.
- Dabney, W., et al. (2018). Implicit Quantile Networks for Distributional Reinforcement Learning. ICML.
- Haarnoja, T., et al. (2018). Soft Actor-Critic Algorithms and Applications. arXiv:1812.05905.
- Fujimoto, S., Hoof, H., and Meger, D. (2018). Addressing Function Approximation Error in Actor-Critic Methods. ICML.
- Sun, P., Zhou, W., and Li, H. (2020). Attentive Experience Replay. AAAI.
- Zha, D., et al. (2019). Experience Replay Optimization. arXiv:1906.08387.
- Sujit, S., et al. (2023). Prioritizing Samples in Reinforcement Learning with Reducible Loss. NeurIPS.
- Dubey, R., et al. (2018). Investigating Human Priors for Playing Video Games. arXiv:1802.10217.